
Radically efficient new architecture - whole codebases and long running agents. Delivered at a reduced infrastructure, cost and energy footprint.
Teams building in context


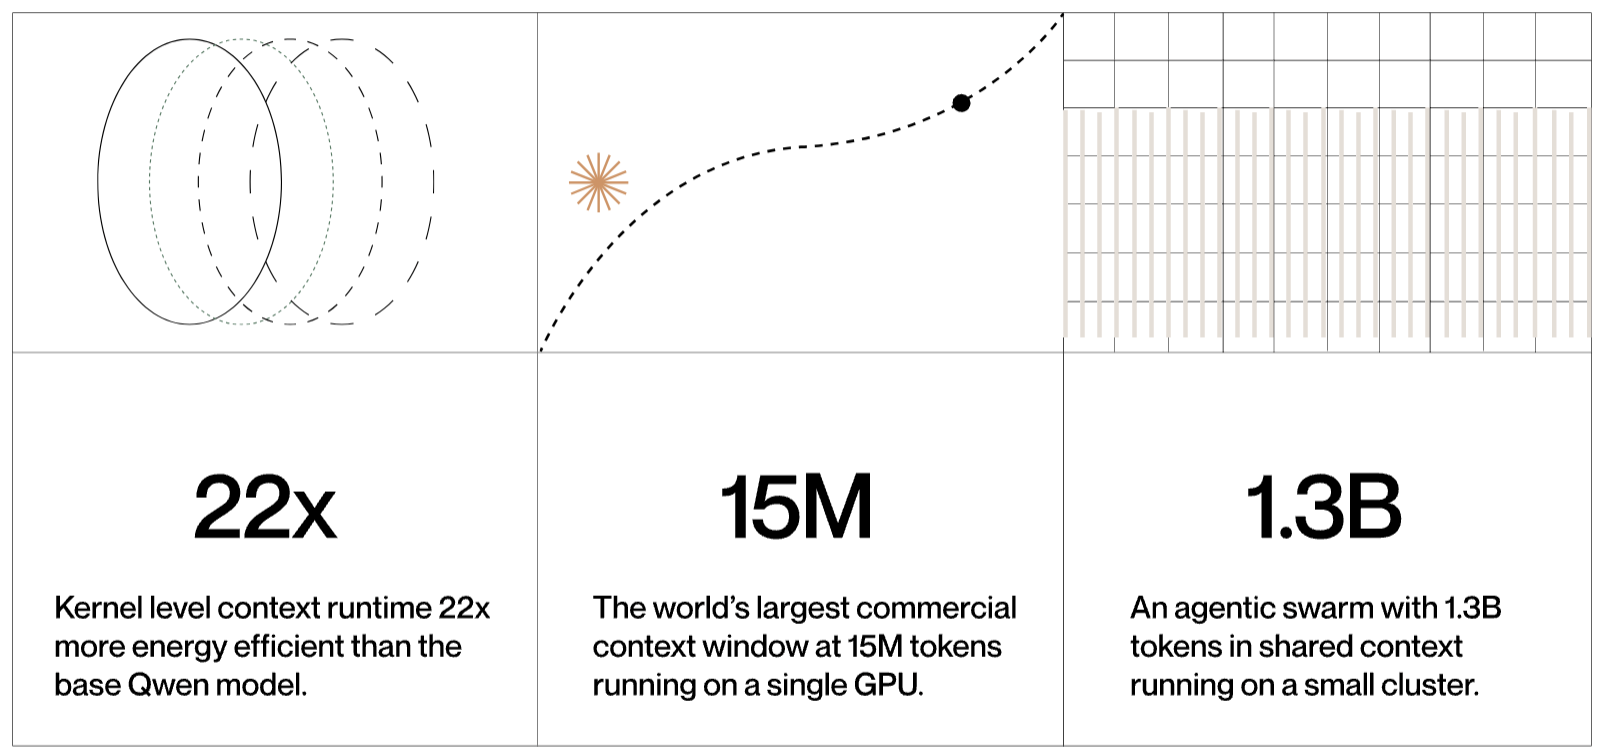
Refiant compresses models and expands context windows to fit on single GPUs and edge devices, maximising throughput with minimum latency. Access this capability via the Refiant platform.
Find Out More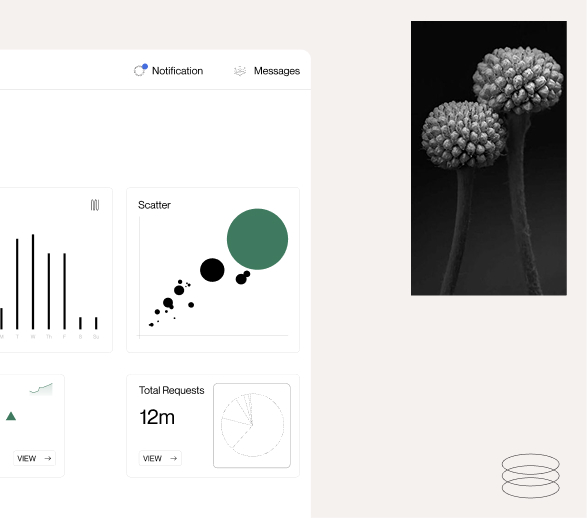




Refiant finds and focuses only on what matters efficiently, ensuring compute is used optimally.

Tokens in context

Hold approximately 7.5 million words in context or 15,000 pages back to back. That's 5 years worth of email or Slack messages.

Reason over 10 years worth of reports in a single session. Ideal for handling compliance and complexity.
Run AI agents 24/7/365 with real-time data inputs held in context.


